Software · QORINAI proprietary platform
Your own AI, inside your own network.
IntraLLM is QORINAI's turn-key enterprise-AI platform — everything an IT department needs to inference and train its own large language and multimodal models on-premises or in a dedicated private cloud. Hardware, GPU orchestration, model repository, assistants, automation and assurance: one console, one vendor, and your data never leaves the building.
Why it exists
Every enterprise will need to train and mature its own AI models. The question is whether that knowledge stays inside the company — or leaks out through a public API.
- 01 · IP RETENTIONKnowledge that stays when people leave
When staff move on they take know-how with them. Models trained inside the network turn that experience into a permanent, queryable company asset.
- 02 · VALUE CREATIONEvery automated workflow adds enterprise value
Owning the models means IT can streamline, automate and quality-assure process after process — the business does more with less, and the capability compounds.
- 03 · SOVEREIGNTYCompliance by architecture, not by contract
No enterprise data or prompts are sent to external proprietary LLMs, so privacy, data-protection and sovereignty obligations are met without relying on a vendor's promise.
- 04 · SECURITYAn AI model that defends the network it lives in
Run cyber-assurance workloads from the safety of your own perimeter — the model inspects your logs, configurations and tickets without any of it going offsite.
- 05 · ECONOMICSPredictable cost at enterprise scale
Per-token API bills grow with every user and every agent. Dedicated GPUs in your own hall or a QORINAI tenancy give a flat, forecastable cost per month.
- 06 · LATENCY & BANDWIDTHKeep the data next to the GPUs
Moving very large datasets across the internet is slow, costly and starves GPUs of work. Inference and training beside the data keeps utilisation — and energy efficiency — high.
Platform modules
Seven enterprise-AI functions in one console.
IntraLLM is organised the way an IT department buys and operates: business-facing modules on top, model management in the middle, cluster operations underneath.
The stack
Bottom-up, from the GPU to the user.
Most "enterprise AI" products are a chat window that calls someone else's API. IntraLLM is the whole stack, so the hardware, the scheduler, the models and the interface are engineered and supported together.
PROPRIETARY PLATFORM · QORINAI PTY LTD · DEVELOPED WITH HYPERSCALERS
- L1Hardware
GPU servers from Australian stock — NVIDIA HGX B300 / H200 / H100 NVL, AMD Instinct, RTX PRO — configured and burned in by Hyperscalers, deployed by QORINAI.
- L2Clustering & GPU job orchestration
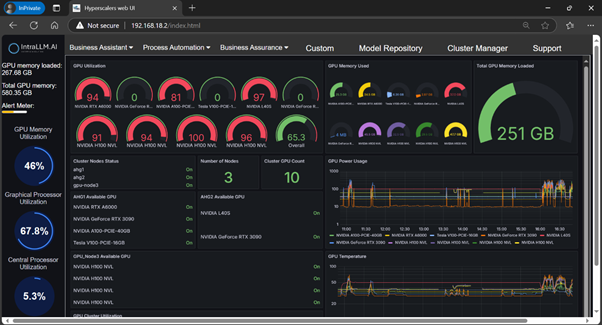
Multi-node scheduling of inference and training jobs, with per-GPU telemetry, alerting and capacity planning in the console.
- L3Transformers & custom extensions
The serving and fine-tuning runtime, quantisation (INT8 / FP8), retrieval pipelines and connectors into enterprise systems.
- L4Model repository
Curated pre-trained LLM and LMM models, plus your own — versioned, access-controlled and served from inside the network.
- L5Interfaces for admins and user groups
Web console for IT; assistants, agents and the SQL Agent for business users; APIs for developers — all behind your identity provider.
Proof points
What the platform does in practice.
Multimodal on-premises — GLM-4.6V
Native image, document and video understanding with a 128K context window: roughly 150 pages of technical documents or an hour of video in a single pass. Reads SAP, CRM and ticketing screens directly, interprets construction drawings and network diagrams, and generates code from UI screenshots.
DESKTOP CAPTURE · DRAWINGS · VISUAL AUDITNatural language to SQL — SQL Agent
"Which products have never been purchased?" becomes an optimised query, executed locally and explained in plain language. Users can view, copy and refine the generated SQL; every byte stays inside the organisation — built for finance, healthcare and government.
AIR-GAPPED · 5 SQL DIALECTSAgents that drive real systems
Browser and desktop automation driven by natural-language instructions — configuring products on a vendor website, completing enquiry forms, extracting data from legacy applications — running on local models with no data leaving the network.
BROWSER-USE · RPA WITHOUT SCRIPTSWhy software matters to a data-centre company
The hall is the asset. The platform is the reason to fill it.
Demand for the halls we build
Every IntraLLM deployment is a GPU node that needs power, cooling and operations. Software turns a colocation conversation into a workload conversation — and workloads are what fill racks.
Recurring revenue on top of capacity
Space and power are priced per kilowatt and compete on rate. A platform is priced per seat, per model and per outcome, adds an annuity to the hosting contract, and makes a customer far harder to move.
One accountable operator, end to end
QOR is the core, IN is the intelligence layer, AI is what runs on top. IntraLLM is the "IN" — the same team that designed the cooling loop also operates the model serving it, so there is one SLA from the substation to the answer.
Rent someone else's model
- Prompts and documents leave the country
- Per-token cost grows with every user and agent
- Provider can change, throttle or retire the model
- Your interactions may train their next model
- No control over where inference physically runs
Own the model, the GPUs and the data path
- Runs in your hall, a QORINAI private tenancy or the sovereign cloud
- Flat monthly cost on dedicated GPUs, billed in AUD
- Open-weight and proprietary models under your version control
- No training on your data — ever
- Australian hardware, warranty, engineers and SLA
How it is delivered
Three ways to run IntraLLM.
Which models are included?
The repository ships with curated open-weight large language and multimodal models — GLM-4.6V, Qwen 2.5 and DeepSeek-class reasoning models among them — and is updated as new releases are validated on the supported hardware. Your own fine-tuned or proprietary models sit alongside them in the BYOM section.
What hardware does it run on?
NVIDIA HGX B300 / B200, H200, H100 NVL, L40S and RTX PRO systems, and AMD Instinct MI325X, all from the Hyperscalers catalogue. A single H200 comfortably serves a quantised 72B model; larger fleets are scheduled by the cluster manager.
Does anything leave our network?
No. Inference, fine-tuning, retrieval and the SQL Agent all run on your GPUs. Fully air-gapped installations are supported; updates are delivered as signed packages.
How is it priced?
Platform licence per deployment plus the hardware or hosting underneath it. Ask for a configuration — we quote the appliance, the tenancy and the cloud option side by side.
See IntraLLM on real GPUs.
Test-drive the platform in HyperLabs or on a QORINAI tenancy with your own documents and databases.